Let your applications speak and understand your customers
SintelSES combines text-to-speech (TTS) and speech-to-text (STT) capabilities on a single platform. It offers a flexible infrastructure for various needs, from voice alerts to call center applications, recording analysis to live speech recognition.
With Turkish-focused voice models and multilingual options, it enables you to develop solutions suited to your organization's language, usage scenario, and technical infrastructure.
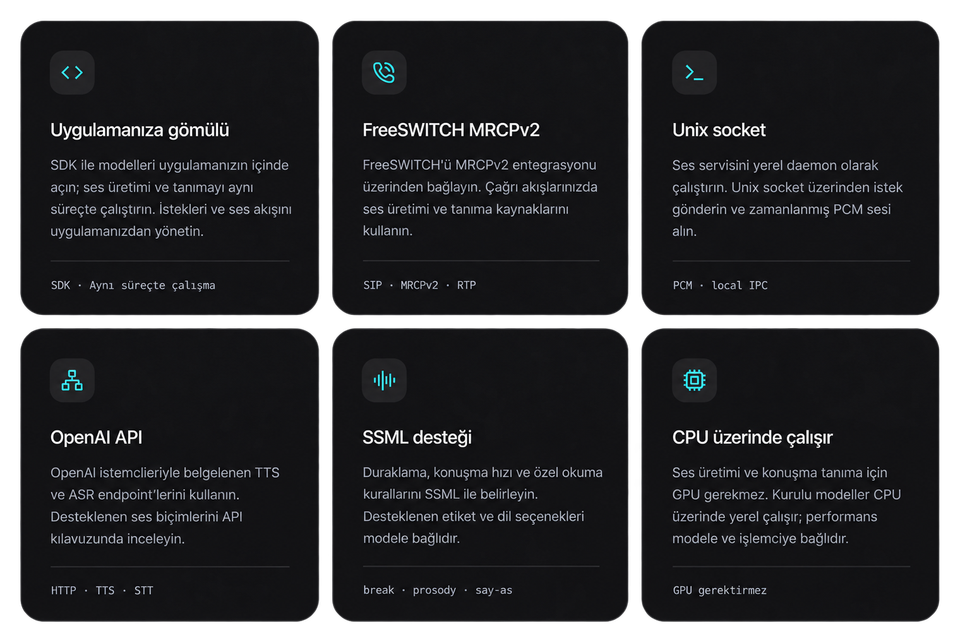
Run in a virtual environment without requiring GPU
SintelSES performs speech synthesis and recognition processes on the CPU. It can be used in compatible virtual machine environments without needing a dedicated GPU or GPU passthrough configuration. Thus, you can deploy it leveraging your existing virtualization infrastructure.
Processing and memory resources are planned based on the selected models, the number of concurrent processes, and the targeted response time.
Convert your texts to speech
Deliver welcome messages, announcements, notifications, and application content audibly. Choose from available voice options that suit your usage; adjust speech speed and reading style in supported models.
- Speech synthesis in Turkish and multilingual voices
- Model and voice options suitable for different needs
- Streamed speech production
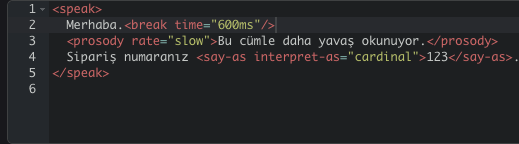
- Pause, speed, and custom reading control with SSML in supported models
Convert speech to text
Transform audio files and microphone inputs into written content. Follow along as speech is processed with models supporting live streaming; evaluate the resulting text in your workflows.
- Extract text from audio files
- Speech recognition via microphone
- Live interim and final text results in supported models
- Turkish, multilingual recognition, and automatic language detection depending on the model chosen
Your voice data processed on your infrastructure
SintelSES performs speech synthesis and recognition locally. Once models are set up, these processes do not require internet connection or external cloud services.
By running on your own servers, you can control the processing of your voice data and reduce reliance on external services. Its CPU-compatible design offers deployment options without the need for a GPU.
Integrate with your existing systems
You can use SintelSES as an independent service or integrate it into your Go applications via SDK.
- Telephone and call center systems: FreeSWITCH integration via MRCPv2
- Web and enterprise applications: Integration with supported endpoints of the OpenAI-compatible voice API
- Live speech recognition: Audio streaming and text results via WebSocket
- Local applications: Service connection via Unix socket
- Go projects: Standalone SDK that can be embedded within applications
Through the web interface, you can synthesize texts into speech, or convert audio files and microphone inputs into text to test your deployed models.
Where is it used?
- Call centers and IVR: Dynamic greeting, routing, and informational messages
- Corporate notifications: Voice delivery of text-based announcements
- Recording analysis: Converting audio content into searchable and editable text
- Digital services: Adding voice input and voice content features to applications
- Multilingual communication: Speech synthesis and recognition in various languages
Language, voice, and streaming features vary depending on the selected model and setup scope.
Let's determine the right voice solution for your organization together
Contact us to evaluate suitable models, deployment, and integration options for your use case.